Skip to content

Every DeepSeek AI Model Explained and Compared (Nov, 2026)

Matt Li By Matt Li, Co-Founder and Director 10 min read
Every DeepSeek AI Model. Every DeepSeek AI Model Explained and Compared (Sep, 2026), by Second Talent.
TL;DR: As of November 2026, the DeepSeek API runs on two models: deepseek-flash (V4.1-Flash-1017) at $0.30 input and $1.20 output per million tokens at peak, and V4-Pro at $1.32/$3.96. Off-peak rates are half price. Both have a 1M context window and a thinking mode, which is where the old R1 reasoning lives. Flash now reads images too. The open weights are MIT licensed, so you can self-host them for free.

DeepSeek’s whole story is strong models at a very low price. There are two ways to use it.

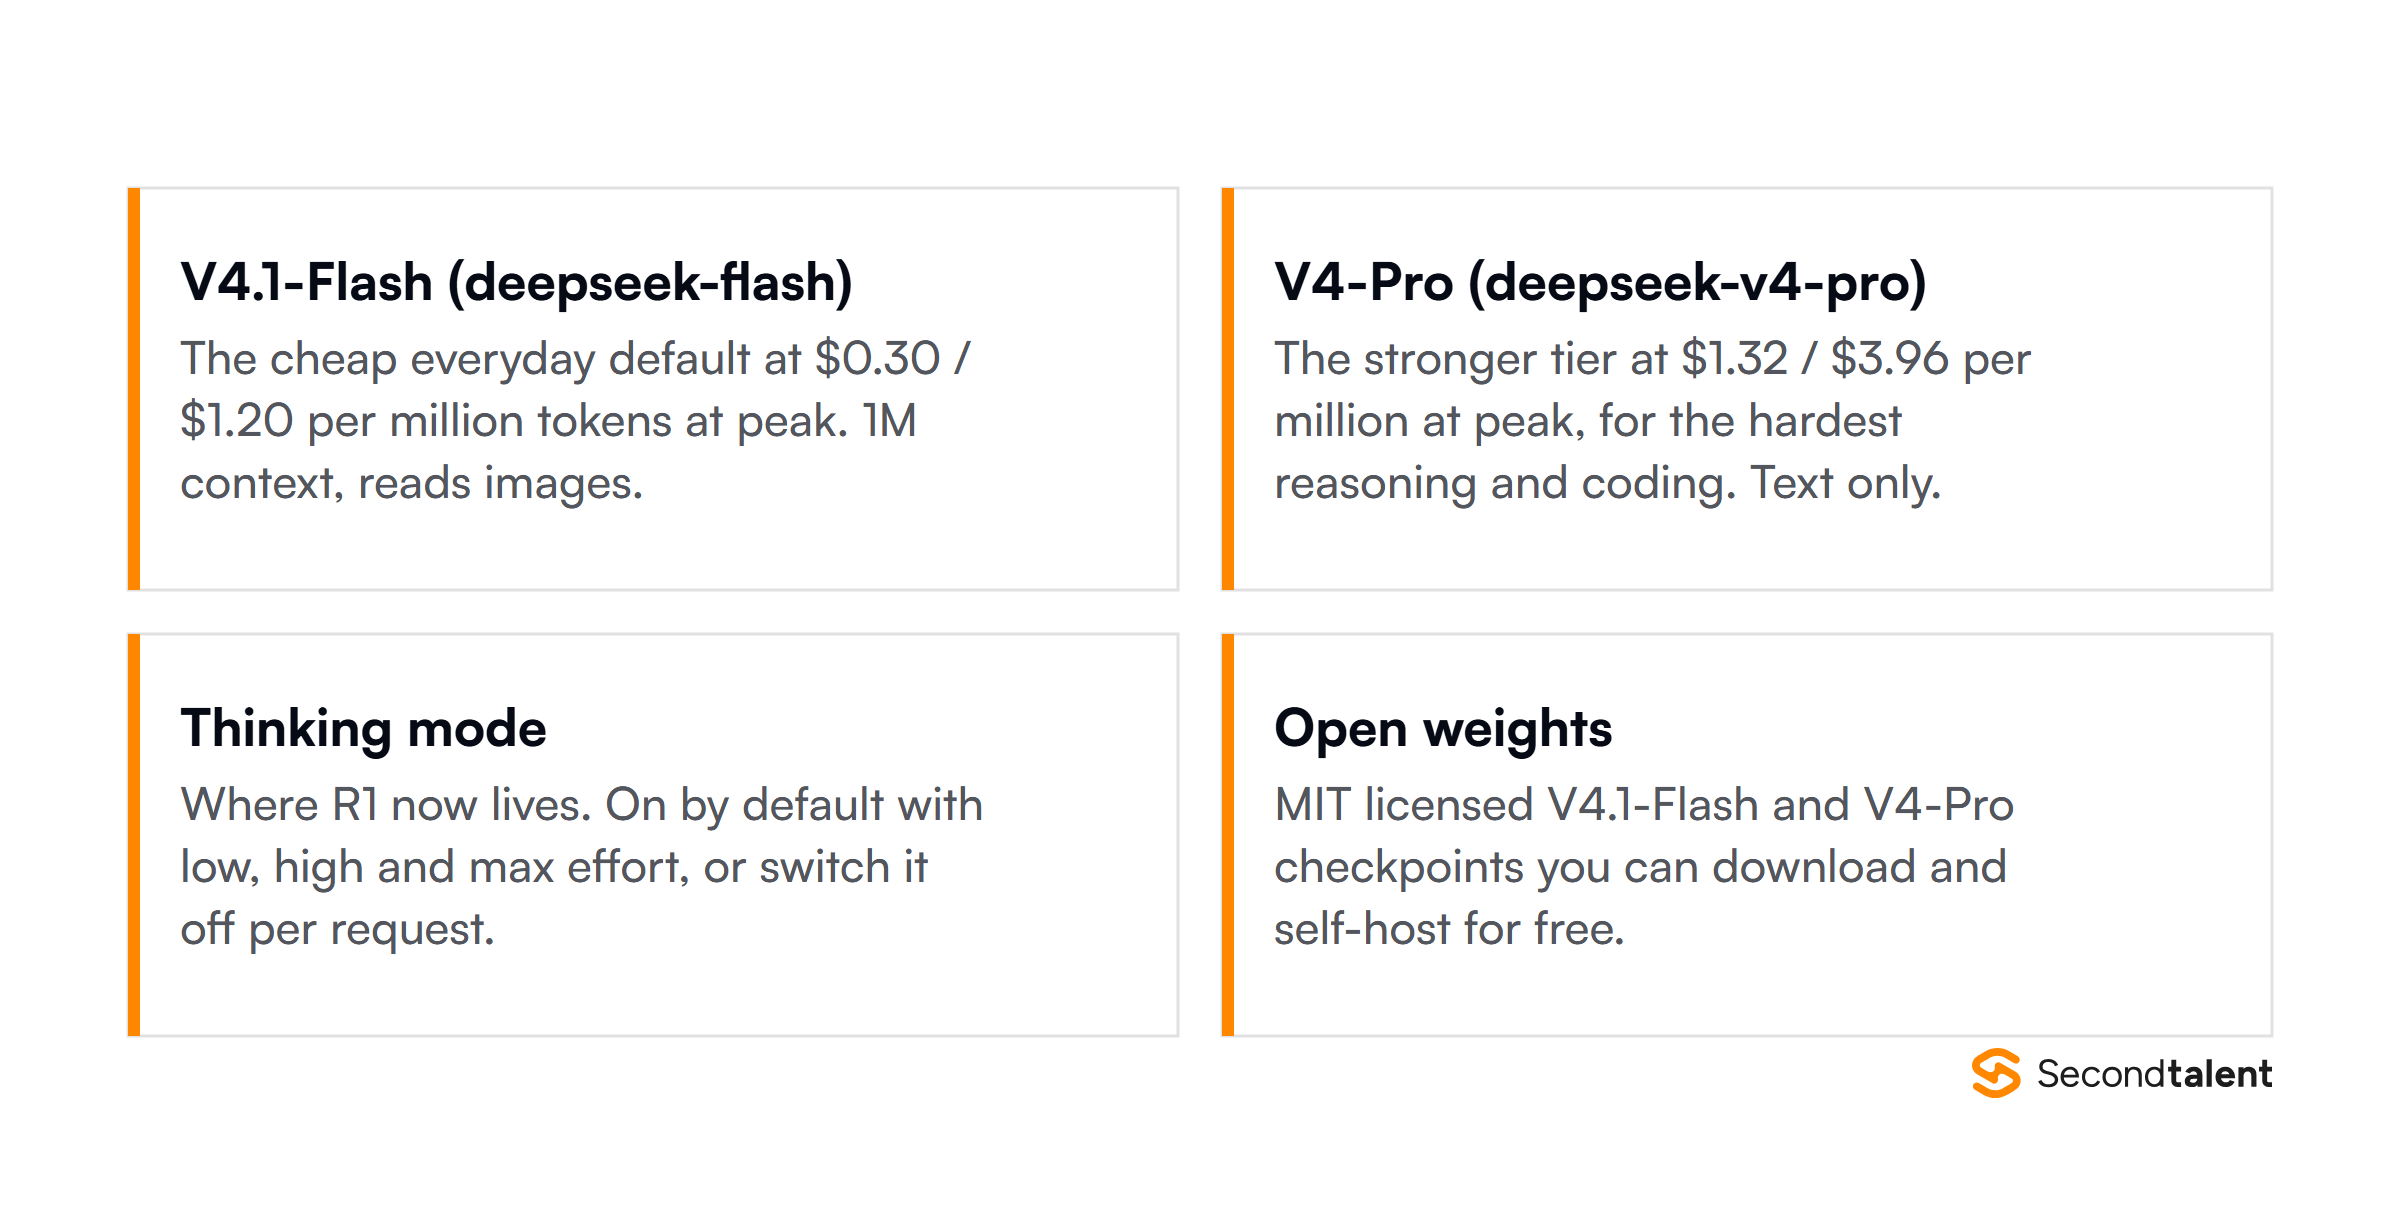
The API runs on two models: V4.1-Flash (called as deepseek-flash) is the cheap everyday default, and V4-Pro is the stronger tier for the hardest work.

Both include a thinking mode that reasons step by step, which is where the old R1 model now lives. The other way is the open weights, released under the permissive MIT license, which you can download and run on your own hardware for free.

DeepSeek is still several times cheaper than a Western flagship for similar quality, even after its August 2026 price changes, and its weights are MIT licensed, so you can self-host with no restriction.

But running it well needs real engineers. This guide helps your team pick between the API and self-hosting, the same way we match engineers to roles.

Key takeaways

  • Two API models: deepseek-flash ($0.30/$1.20 at peak) for everyday work, V4-Pro ($1.32/$3.96 at peak) for the hardest tasks.
  • Off-peak rates are half the peak rates. Peak is 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays.
  • Both have a 1M context window and up to 384K output. Flash also accepts images, while V4-Pro is text only.
  • Thinking mode is the old R1 reasoning, now on by default with low, high and max effort levels.
  • Cache hits cost $0.006 per million input tokens on Flash at peak, 98% cheaper than a cache miss.
  • The open weights are MIT licensed, so you can self-host V4.1-Flash or V4-Pro with no restriction.
The DeepSeek API models at a glance

Here are the two API models as of November 2026, with the model names your engineers will call. Use this table as your reference. Prices are input then output, per one million tokens, at the cache-miss rate.

Peak prices come first, off-peak prices in brackets. Source: the DeepSeek models and pricing page.

ModelContextPrice in / out (per 1M)Best for
DeepSeek-V4-Pro 1M $1.32 / $3.96 ($0.66 / $1.98) Hardest reasoning and coding
DeepSeek-V4.1-Flash (deepseek-flash) 1M $0.30 / $1.20 ($0.15 / $0.60) The cheap everyday default, with vision
deepseek-v4-flash 1M $0.30 / $1.20 ($0.15 / $0.60) Retired name, routed to V4.1-Flash
Cache hit, Flash (input) N/A $0.006 ($0.003) / N/A Repeated context, near free
Cache hit, V4-Pro (input) N/A $0.044 ($0.022) / N/A Repeated context on Pro

The DeepSeek lineup in plain English

DeepSeek keeps the API simple. There are two models and two modes. V4.1-Flash is the cheap default. V4-Pro is the stronger tier. Each can run in a fast non-thinking mode or a slower thinking mode.

The open weights sit alongside the API for teams that want to self-host. Once you see that shape, the naming stops feeling confusing.

The DeepSeek lineup in November 2026: V4.1-Flash at $0.30 and $1.20 per million tokens, V4-Pro at $1.32 and $3.96, thinking mode and MIT licensed open weights, from DeepSeek docs

V4.1-Flash and V4-Pro

V4.1-Flash is the model most teams should default to. DeepSeek released it on September 10, 2026 and upgraded it to the 1017 version on October 17, 2026. You call it as deepseek-flash, which always points to the latest Flash build.

At $0.30 input and $1.20 output per million tokens at peak, or half that off-peak, with a 1M context window, it handles chat, extraction, tagging, and coding well.

It is also natively multimodal, so it can read screenshots, charts and documents. V4-Pro is the stronger tier at $1.32 input and $3.96 output at peak.

Its GA release landed on August 13, 2026, and it is built for the hardest reasoning and the most demanding coding. V4-Pro is text only.

Even the Pro tier costs a fraction of a Western flagship, which is why cost-sensitive teams favor DeepSeek.

Thinking mode and the R1 story

DeepSeek made its name with R1, a reasoning model that thought step by step. R1 no longer exists as a separate product. Its reasoning now lives inside V4 and V4.1 as a thinking mode.

Thinking is on by default, and you can set the effort to low, high or max, or switch it off per request.

The old deepseek-chat and deepseek-reasoner aliases were scheduled for discontinuation on July 24, 2026, and the current docs no longer list them. Same reasoning quality, one model name.

See the DeepSeek thinking mode guide for the switches.

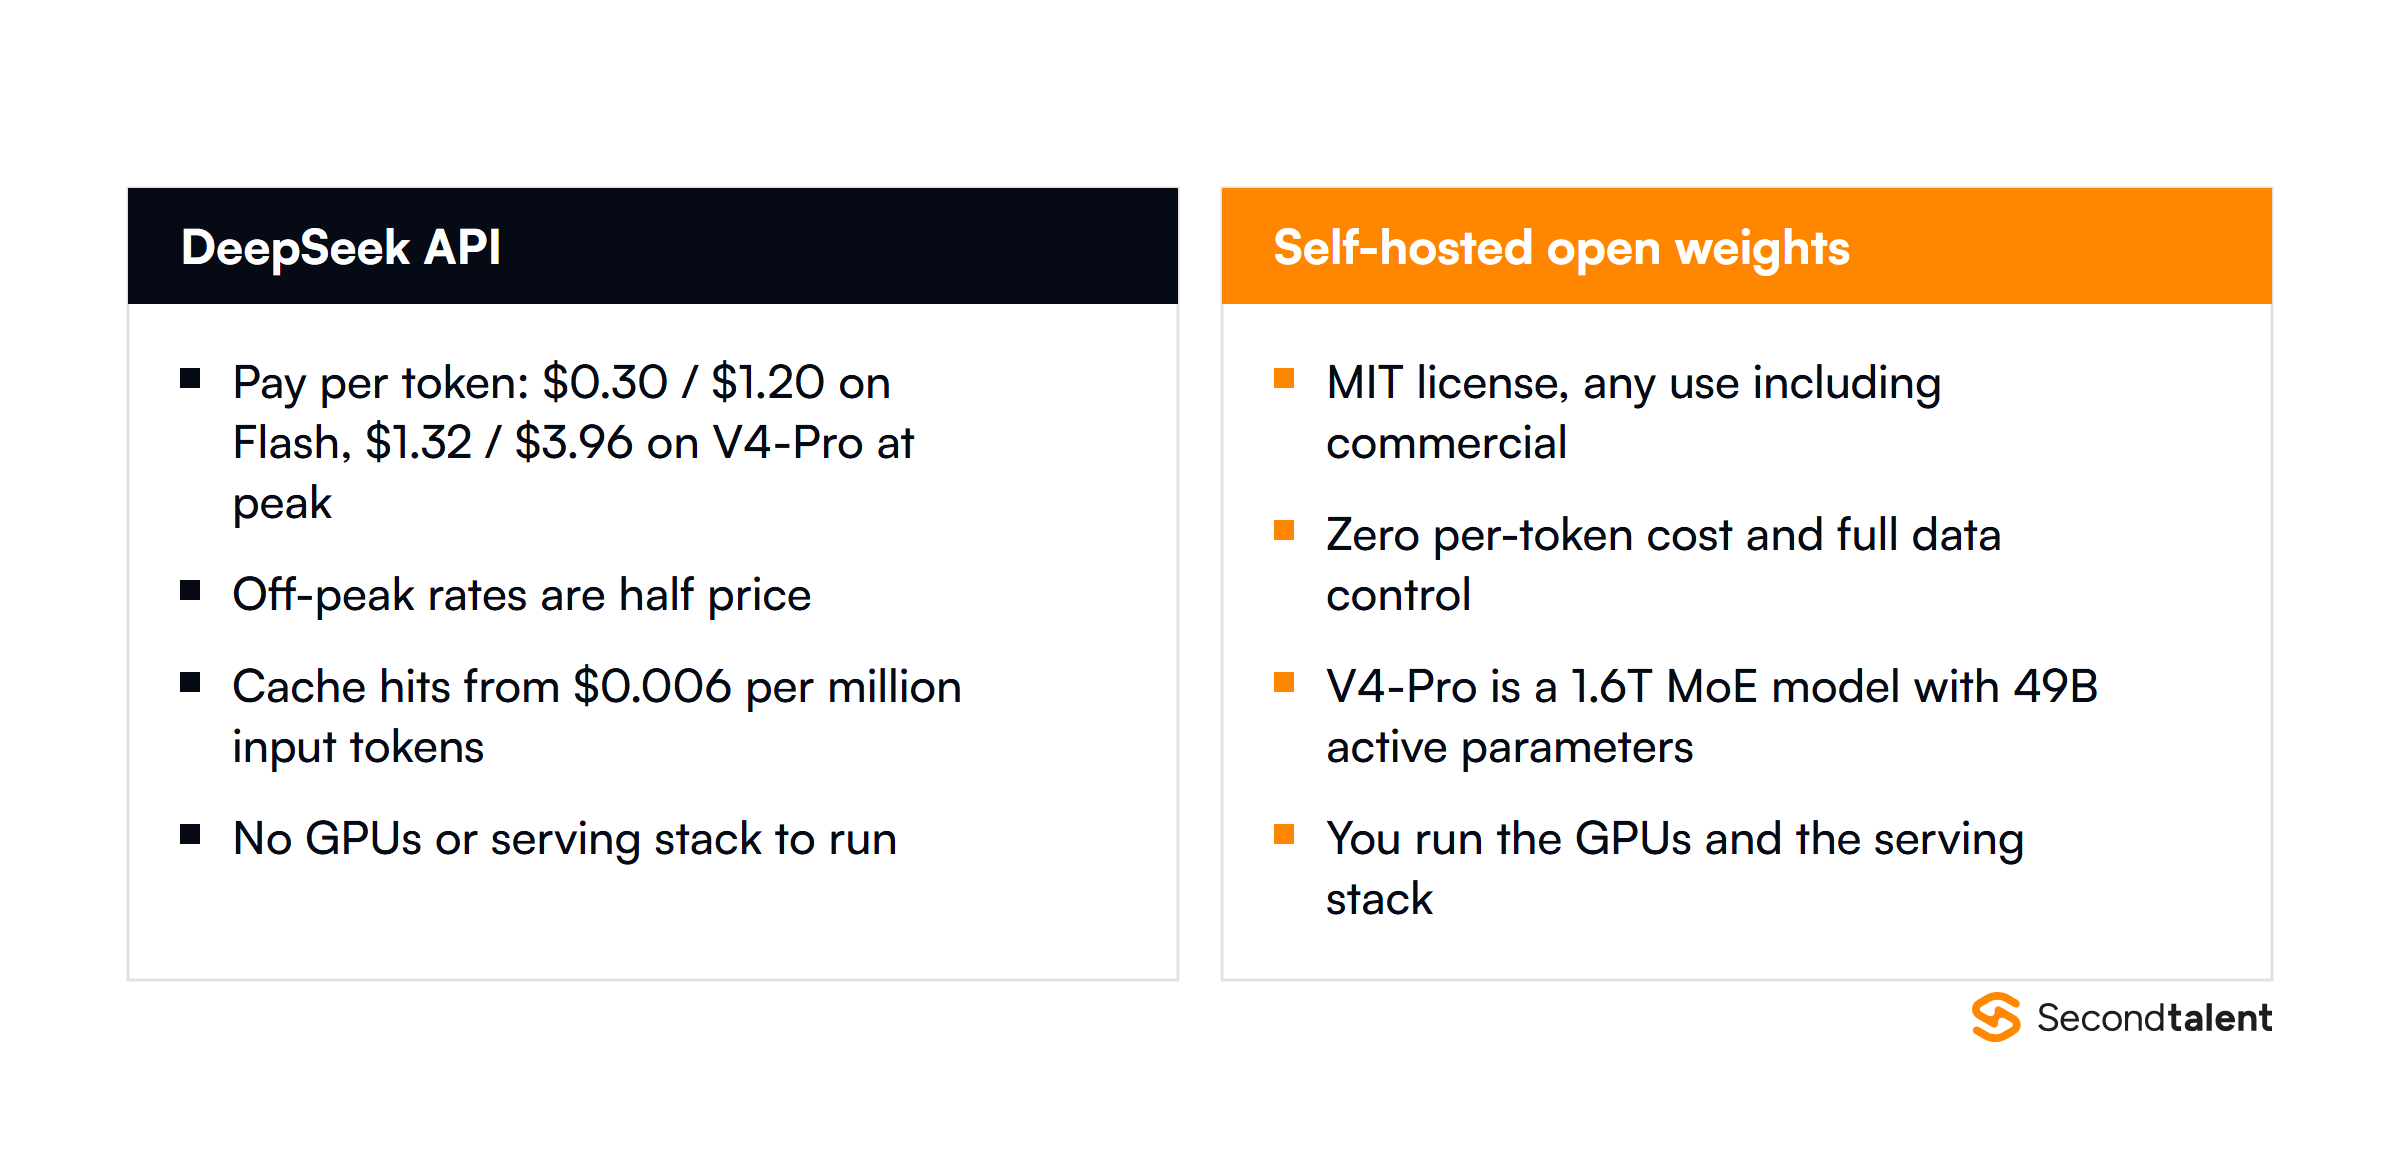
DeepSeek API compared with self-hosted open weights: per-token peak and off-peak pricing and caching against the MIT license, zero per-token cost and running your own GPUs

Open weights and self-hosting

DeepSeek publishes its models as open weights under the MIT license, which is more permissive than most. You can download, modify, and self-host them for any use, including commercial, with no special permission.

The current releases are DeepSeek-V4-Pro, a 1.6T Mixture-of-Experts model with 49B active parameters, and DeepSeek-V4.1-Flash, a multimodal MoE model with 552B backbone parameters that activates 8B parameters per token during prefill and 16B during decode.

The newest Flash checkpoint, V4.1-Flash-1017, is also on Hugging Face. Older models such as V3.2 and R1 remain freely available.

Self-hosting gives you full data control and zero per-token cost, which matters for private data and very high volume. The trade is that you run the GPUs and manage the serving stack. That takes real skill.

Running a 1.6T MoE model efficiently is a job for strong AI and machine learning engineers.

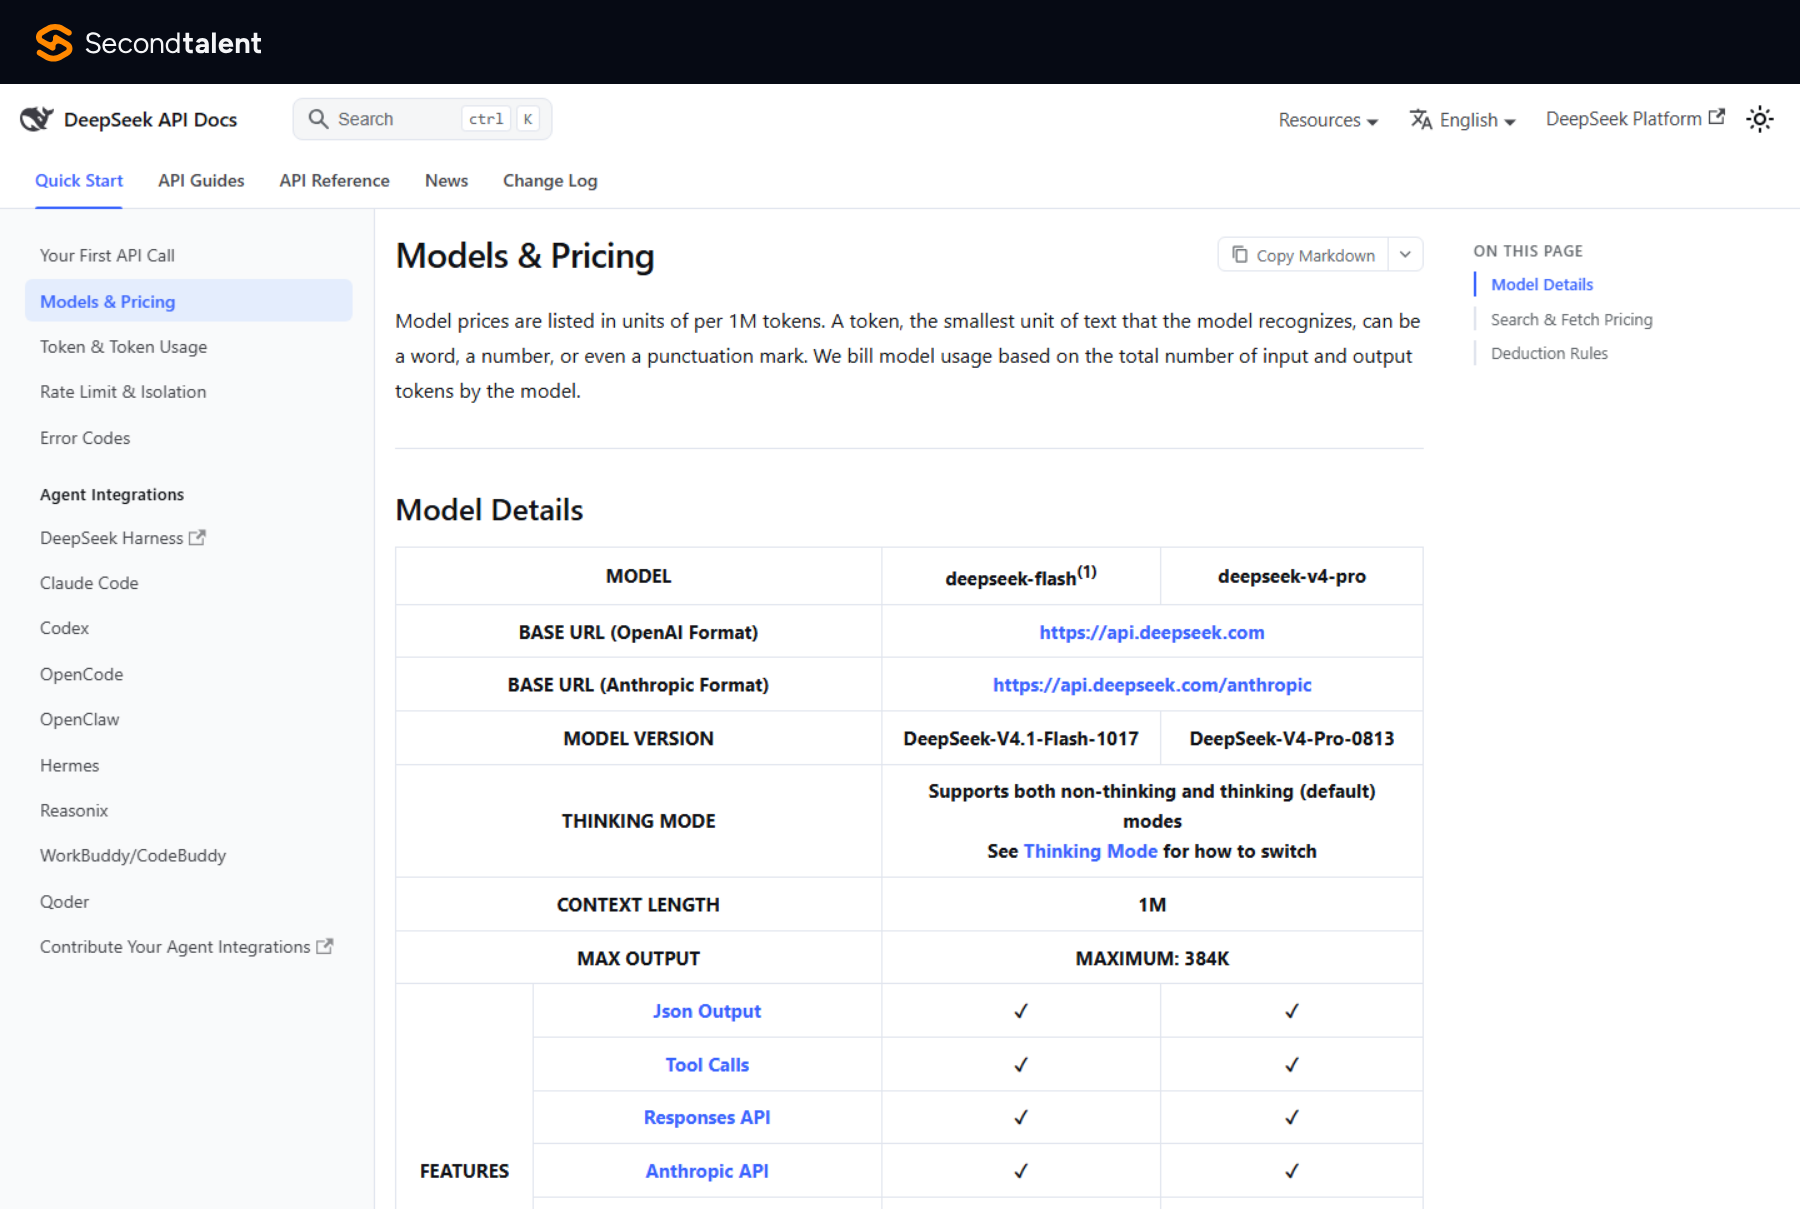
DeepSeek API Models and Pricing docs page listing deepseek-flash (DeepSeek-V4.1-Flash-1017) and deepseek-v4-pro (DeepSeek-V4-Pro-0813) with 1M context and 384K max output

Pricing compared across the lineup

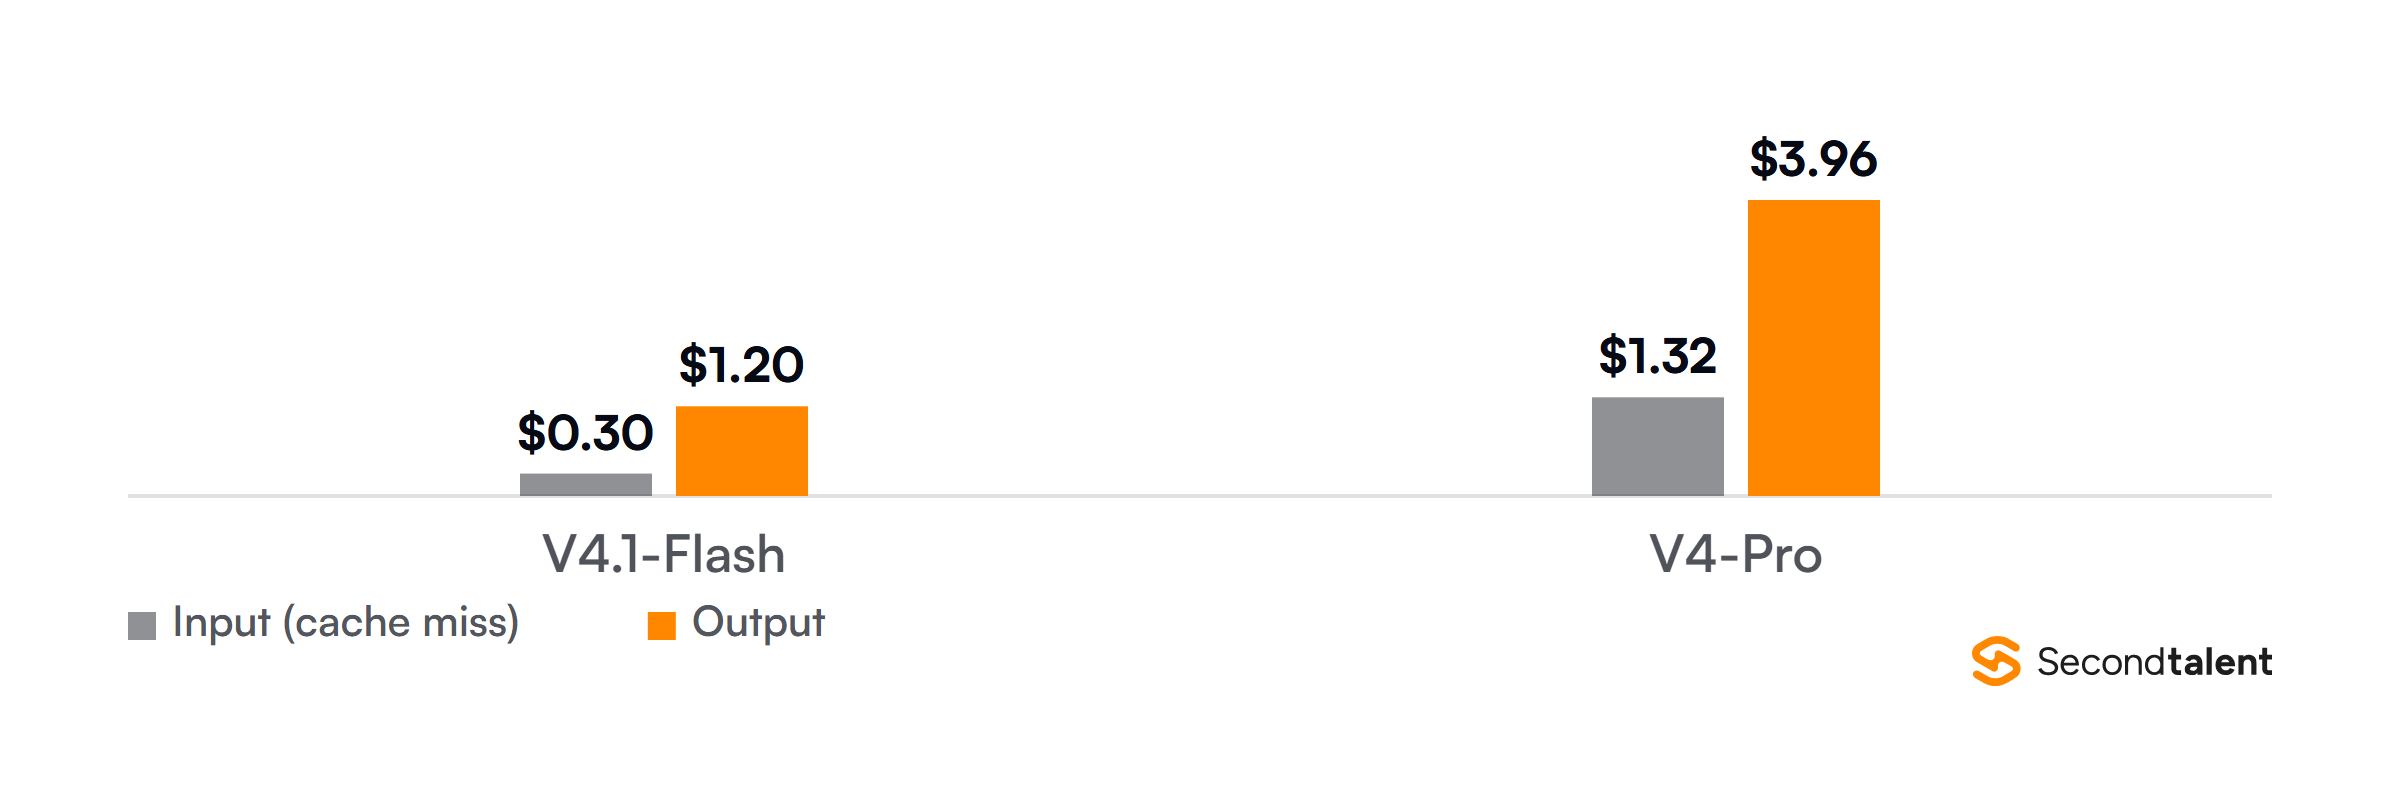
DeepSeek is built to be cheap. Output tokens drive most cost. Flash output is $1.20 per million at peak and $0.60 off-peak, with V4-Pro at $3.96 and $1.98. Both are still far below a Western flagship.

DeepSeek moved to peak and off-peak pricing on August 16, 2026 and cut Flash prices with the V4.1 release, per its API change log. The chart shows input and output price for the two API models.

Peak input and output price per million tokens in November 2026: V4.1-Flash at $0.30 and $1.20, V4-Pro at $1.32 and $3.96, from DeepSeek pricing docs

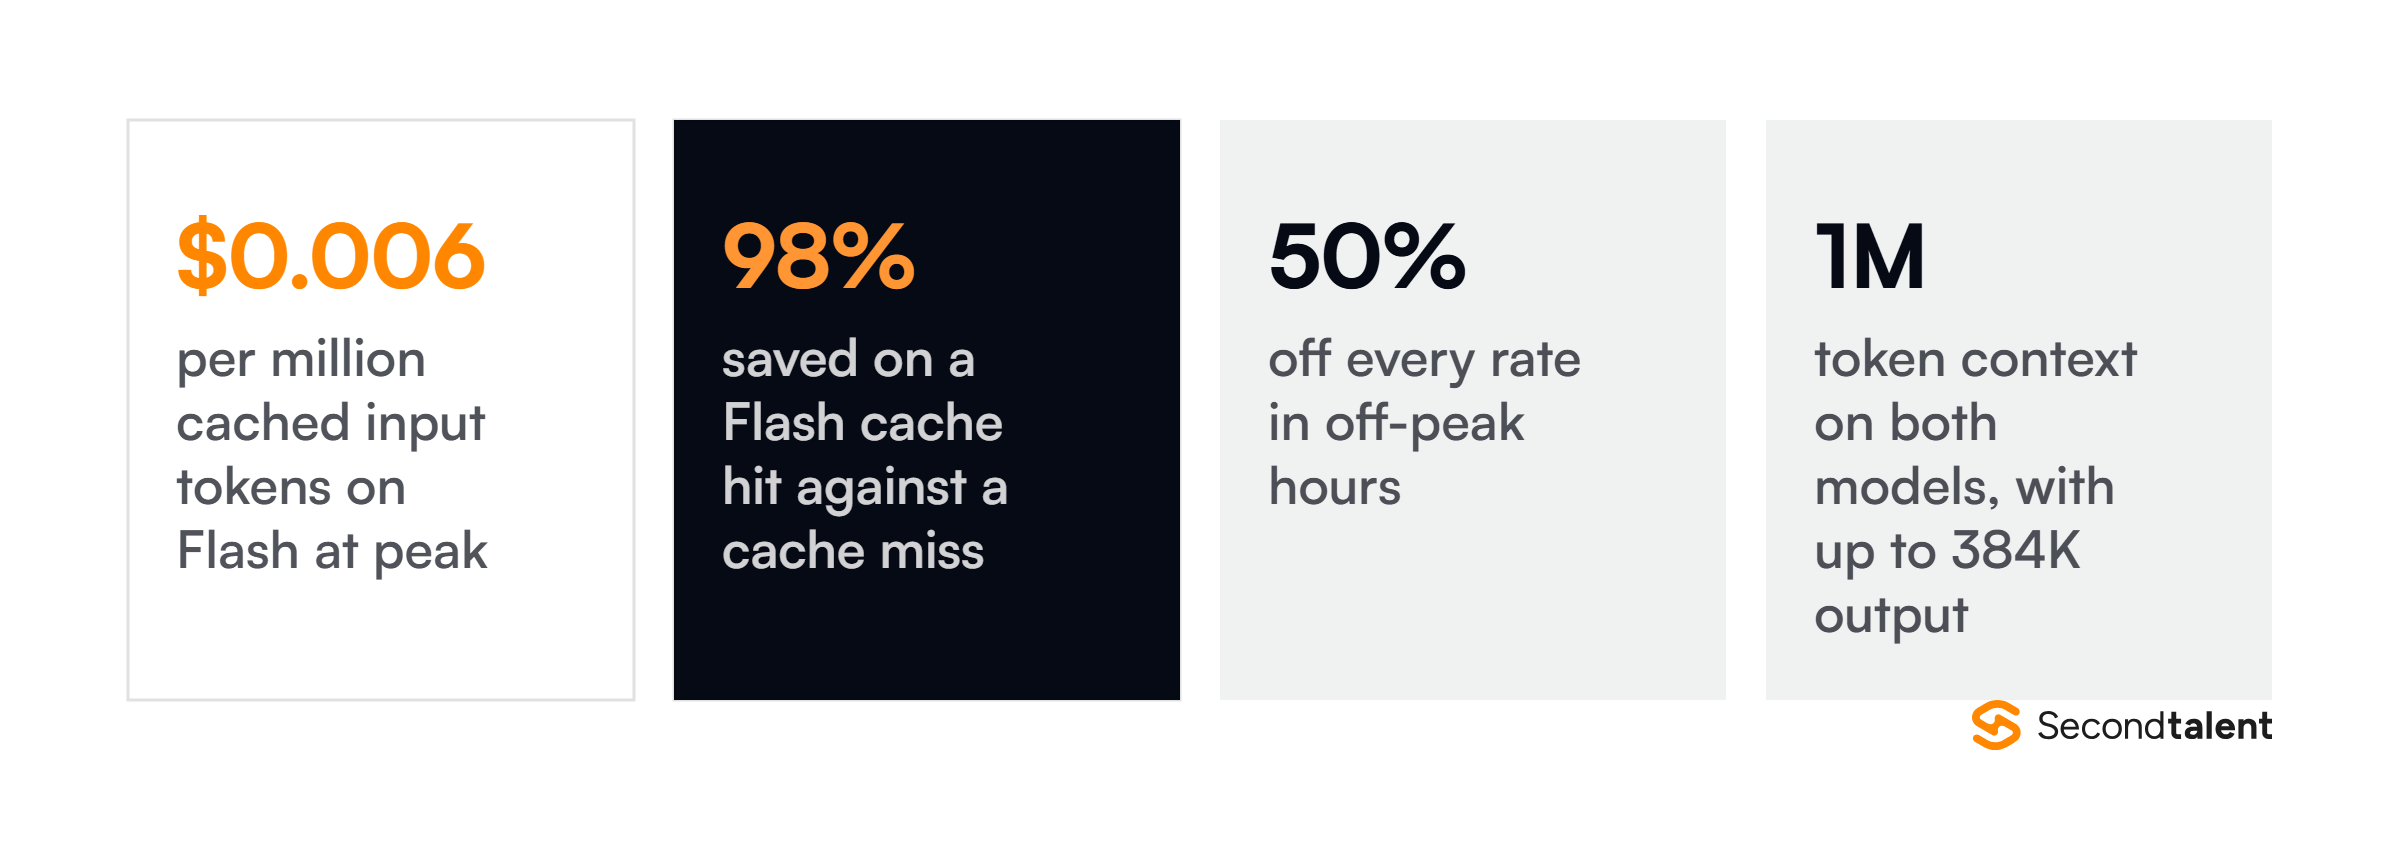
Two extra levers make it cheaper still. Cache hits charge repeated context at $0.006 per million input tokens on Flash at peak, 98% off a cache miss, and $0.044 on V4-Pro. That is huge for agents that reuse a big system prompt.

Off-peak hours halve every rate. Peak runs 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, and weekends and Chinese public holidays are off-peak in full.

Teams that use caching and off-peak batching well cut their bill far below the sticker rate. This is the kind of work that separates a strong AI engineer from an average one.

Key DeepSeek numbers for November 2026: $0.006 per million cached input tokens on Flash, 98 percent saved on a cache hit, 50 percent off-peak discount and 1M context, from DeepSeek pricing docs

Context windows and thinking mode

Both API models offer a 1M token context window, a big jump from the 128K to 164K of the V3 generation. That is roughly 750,000 words, enough for full-codebase reasoning and long multi-document work in a single request.

Max output on both is 384K tokens, so even long generations fit.

Thinking mode is the main quality lever. Turn it on for hard math, code, and logic, where step-by-step reasoning pays off. Leave it off for simple chat and tagging, where speed and cost matter more.

Thinking mode is on by default and uses more output tokens, so it costs more per call. Use the low effort level or switch thinking off for simple work. An engineer who switches modes on purpose runs DeepSeek far cheaper at the same quality.

You can read more in our breakdown of Claude versus ChatGPT for coding.

Which model should you use

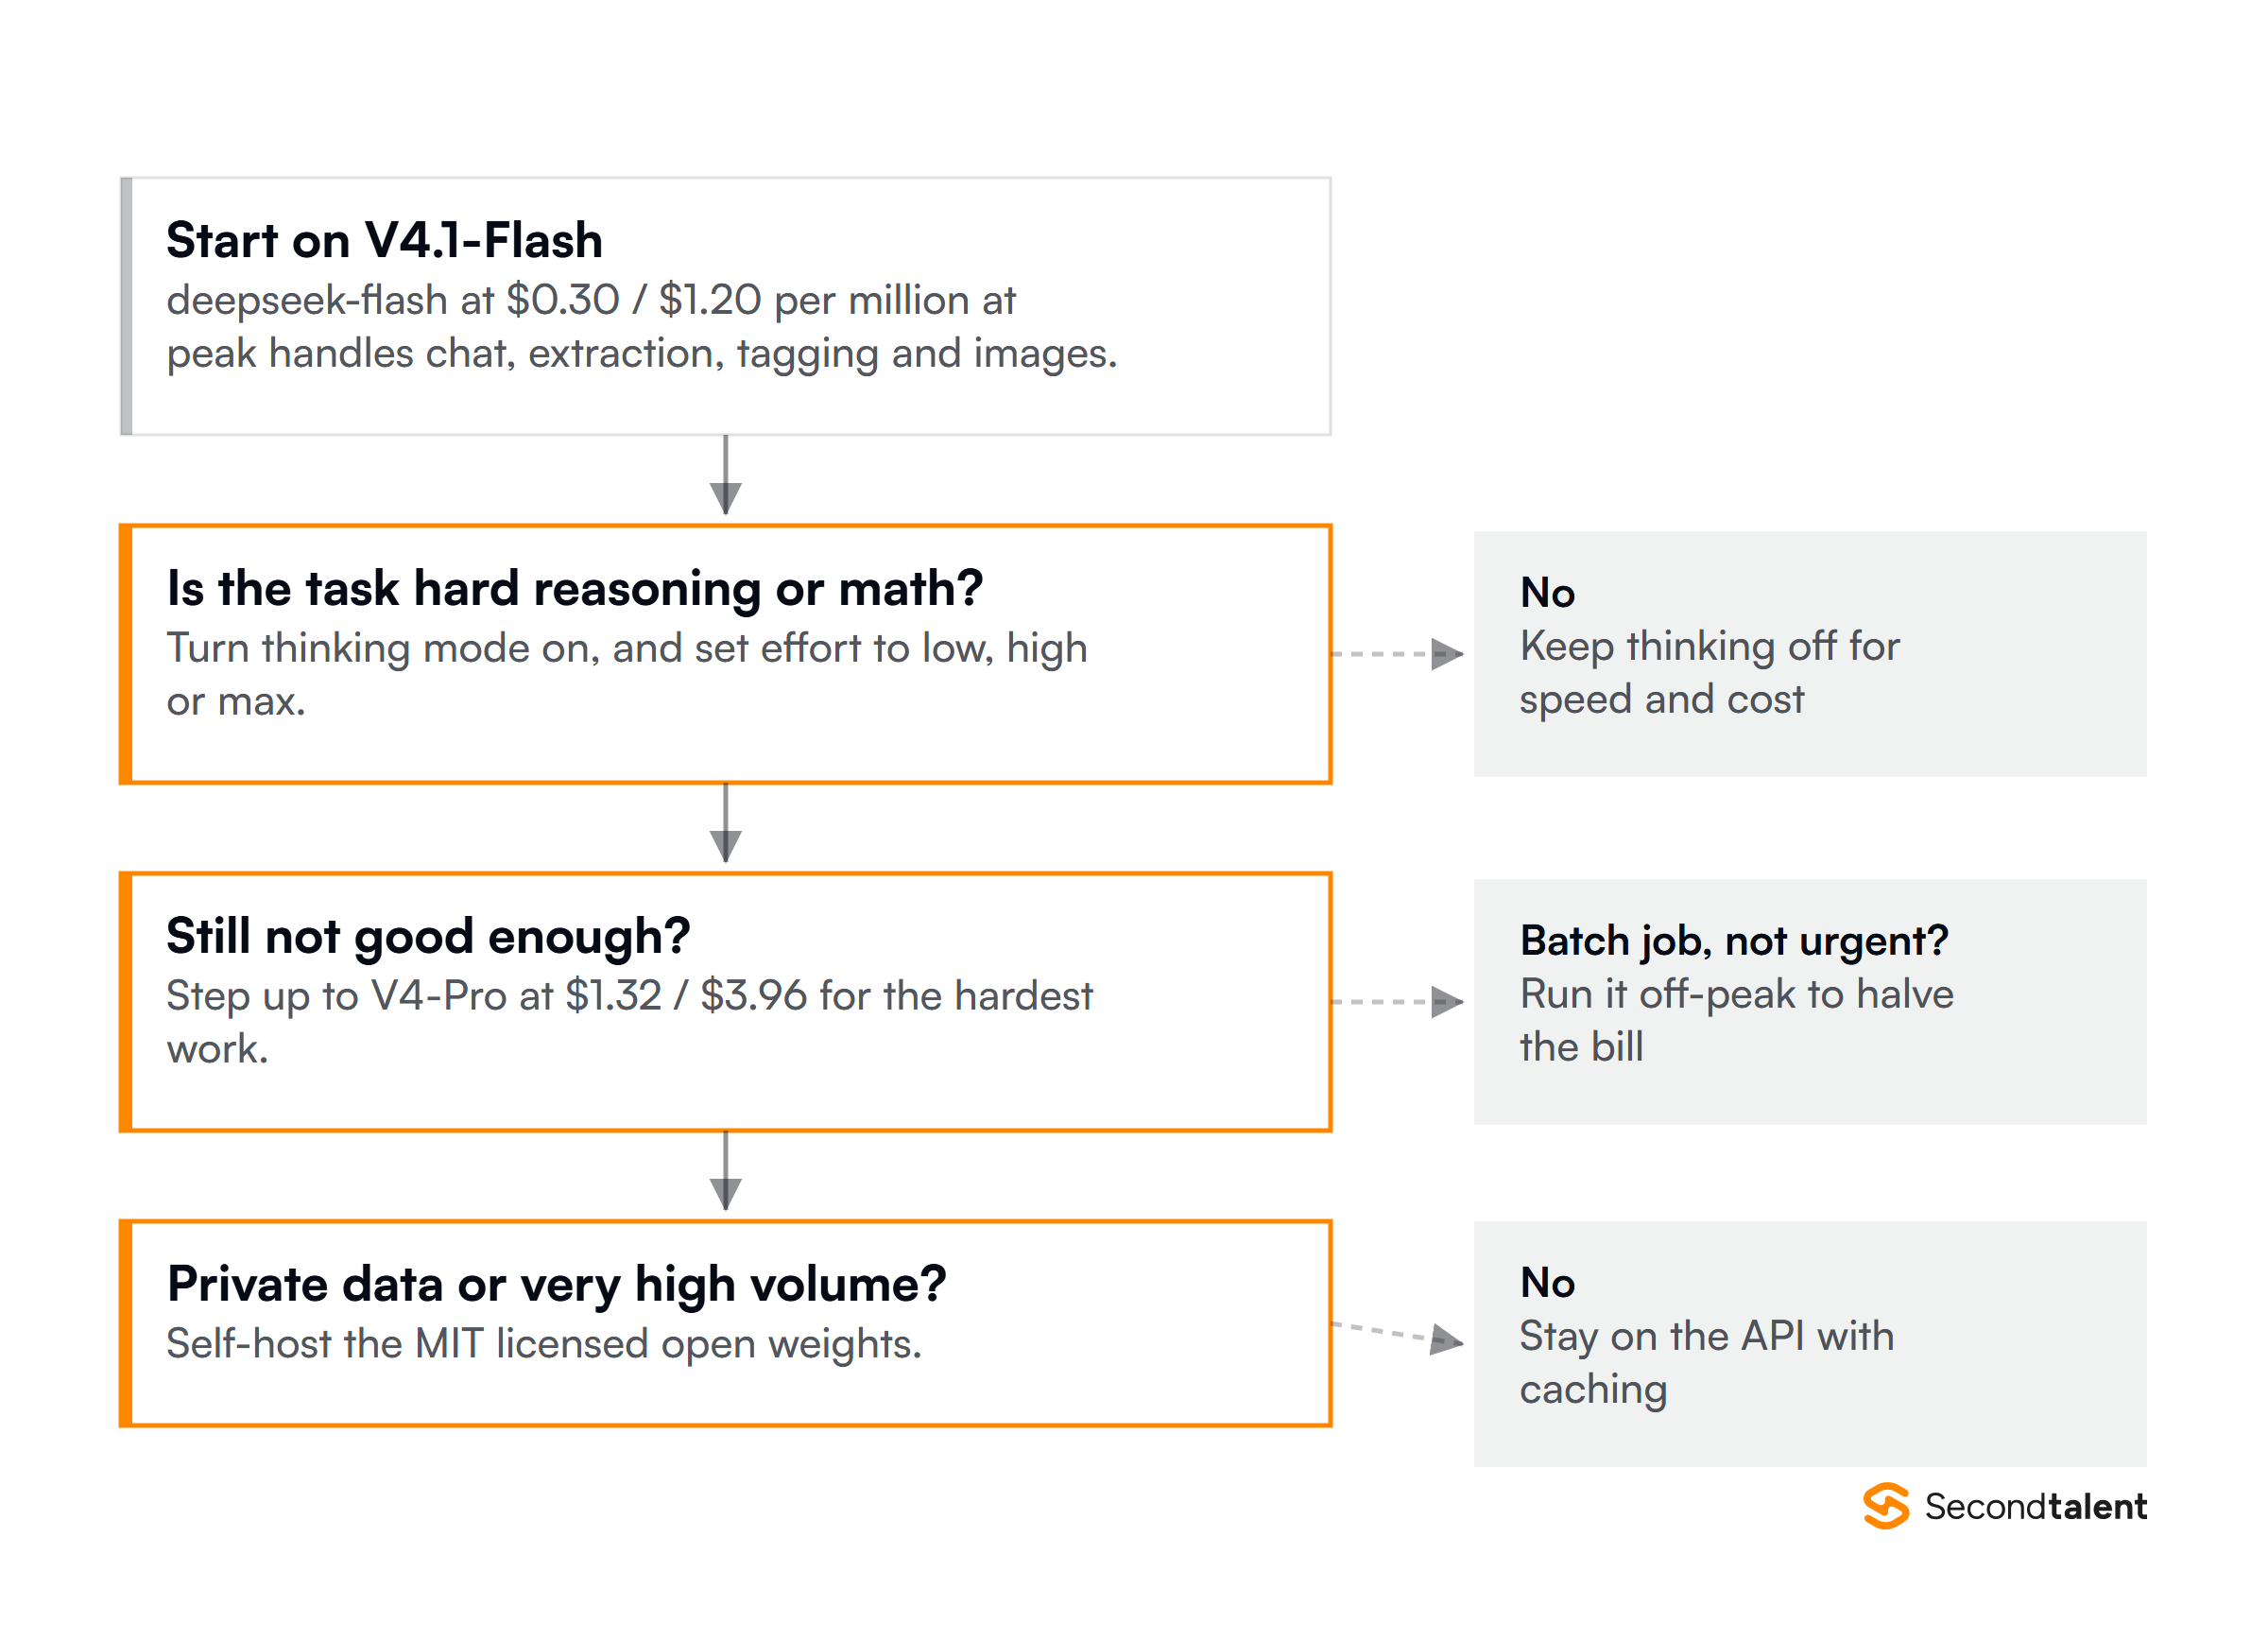
Start with deepseek-flash with thinking switched off. It is the cheap default for most tasks. Turn thinking back on when a task needs reasoning. Step up to V4-Pro for the hardest work. Schedule batch jobs off-peak to halve the bill.

Self-host the open weights when you need data control or run very high volume. The table below maps common jobs to a model.

JobRecommended modelWhy
Support chatbot, FAQ V4.1-Flash (non-thinking) One of the cheapest strong models
Data tagging, extraction V4.1-Flash (non-thinking) Fast, cheap, 1M context
Screenshots, charts, documents V4.1-Flash Native vision, V4-Pro is text only
Math, logic, planning V4.1-Flash (thinking) R1-grade reasoning, low price
Hardest reasoning and coding V4-Pro Stronger tier, still cheap
Private data, high volume V4.1-Flash or V4-Pro (self-host) MIT license, $0 per token
Agents with big prompts V4.1-Flash + caching Cache hits are near free
Decision flow for choosing a DeepSeek model: start on V4.1-Flash, add thinking mode, step up to V4-Pro, run batch jobs off-peak, or self-host the open weights

A simple rule helps. Prototype on V4.1-Flash, measure your real volume, then decide if thinking mode, V4-Pro, off-peak batching or self-hosting pays off. We worked with a team that ran everything on a Western flagship.

Moving routine work to DeepSeek Flash and keeping only the hardest calls on a premium model cut their bill by more than half with no drop in quality.

Older DeepSeek models

DeepSeek ships fast, and older versions are retired quickly. V4-Flash and V4-Flash-Vision-Exp were retired on September 10, 2026, and their names now route to V4.1-Flash. If your code calls an older model or alias, plan to move it.

Use deepseek-flash and deepseek-v4-pro by name. The table shows the main older models and what to use instead.

Older modelStatusMove to
DeepSeek-V4-Flash, V4-Flash-Vision-Exp Retired Sep 10, 2026 deepseek-flash (V4.1-Flash)
DeepSeek-R1 Folded into V4 Thinking mode
DeepSeek-V3, V3.1, V3.2 Superseded on API V4.1-Flash or V4-Pro
deepseek-chat, deepseek-reasoner Discontinuation set for Jul 24, 2026 deepseek-flash by name
DeepSeek-V2, Coder Legacy V4.1-Flash or self-hosted weights

A move is usually small. On the API you change the model name. For open weights you download the new checkpoint and update your serving config.

The DeepSeek API docs and the model cards on Hugging Face show every current and older version in one place, so check them before you migrate.

The deepseek-ai organization page on Hugging Face showing recent DeepSeek-V4.1-Flash-1017 activity and the DeepSeek-V4 collection

What this means for hiring

Knowing the lineup is step one. Getting value from it is the harder step. With DeepSeek the biggest levers are thinking mode, caching, off-peak batching, and the choice to self-host.

The teams that win are the ones who use these well, not the ones on the biggest model. That is engineering, not just a model choice.

Engineers who can deploy and optimize open models are scarce and costly in the United States. A senior AI engineer there runs $12,000 to $18,000 per month all in.

The same skill from a pre-vetted engineer in Vietnam or the Philippines often costs $3,000 to $6,000 per month. The work is the same. The bill is not.

Many of our clients build their whole DeepSeek stack with an AI model deployment engineer from our network.

The DeepSeek organization page on GitHub with its open source repositories, including DeepInfer and deepseek-harness

Build your DeepSeek stack with the right team

DeepSeek gives you strong reasoning at a very low price, plus MIT open weights you can self-host. The model is the easy part. The team that deploys and ships with it is what creates value.

We match you with pre-vetted senior engineers across Asia in about 24 hours, with no upfront cost and payroll handled.

Get developers who ship with AI agents. Starts at $25/Hour.

Start Hiring $0 cost until you hire
Matt Li

Written by

Matt Li is a tech-driven entrepreneur with deep expertise in global talent strategy, digital experience optimization, e-commerce, and Web3 innovation. He is the Co-Founder of Second Talent, a US-based company that connects businesses with top-tier tech professionals worldwide. Since launching the company in 2024, Matt has led its growth by leveraging technology to streamline remote hiring and scale distributed teams. With a background spanning product, operations, and innovation, Matt brings a cross-disciplinary perspective to the evolving digital economy. His work sits at the intersection of global talent, emerging technology, and scalable digital transformation.

More posts by Matt Li →